If you peek under the hood of almost any frontier AI model today, you’ll notice the same thing: a mixture-of-experts, or MoE, architecture. The easiest way to think about it is that it works a lot like the human brain. Instead of firing up the entire network for every task, MoE models activate only the experts relevant to each token, which makes generation both faster and far more efficient without needing proportional increases in compute.
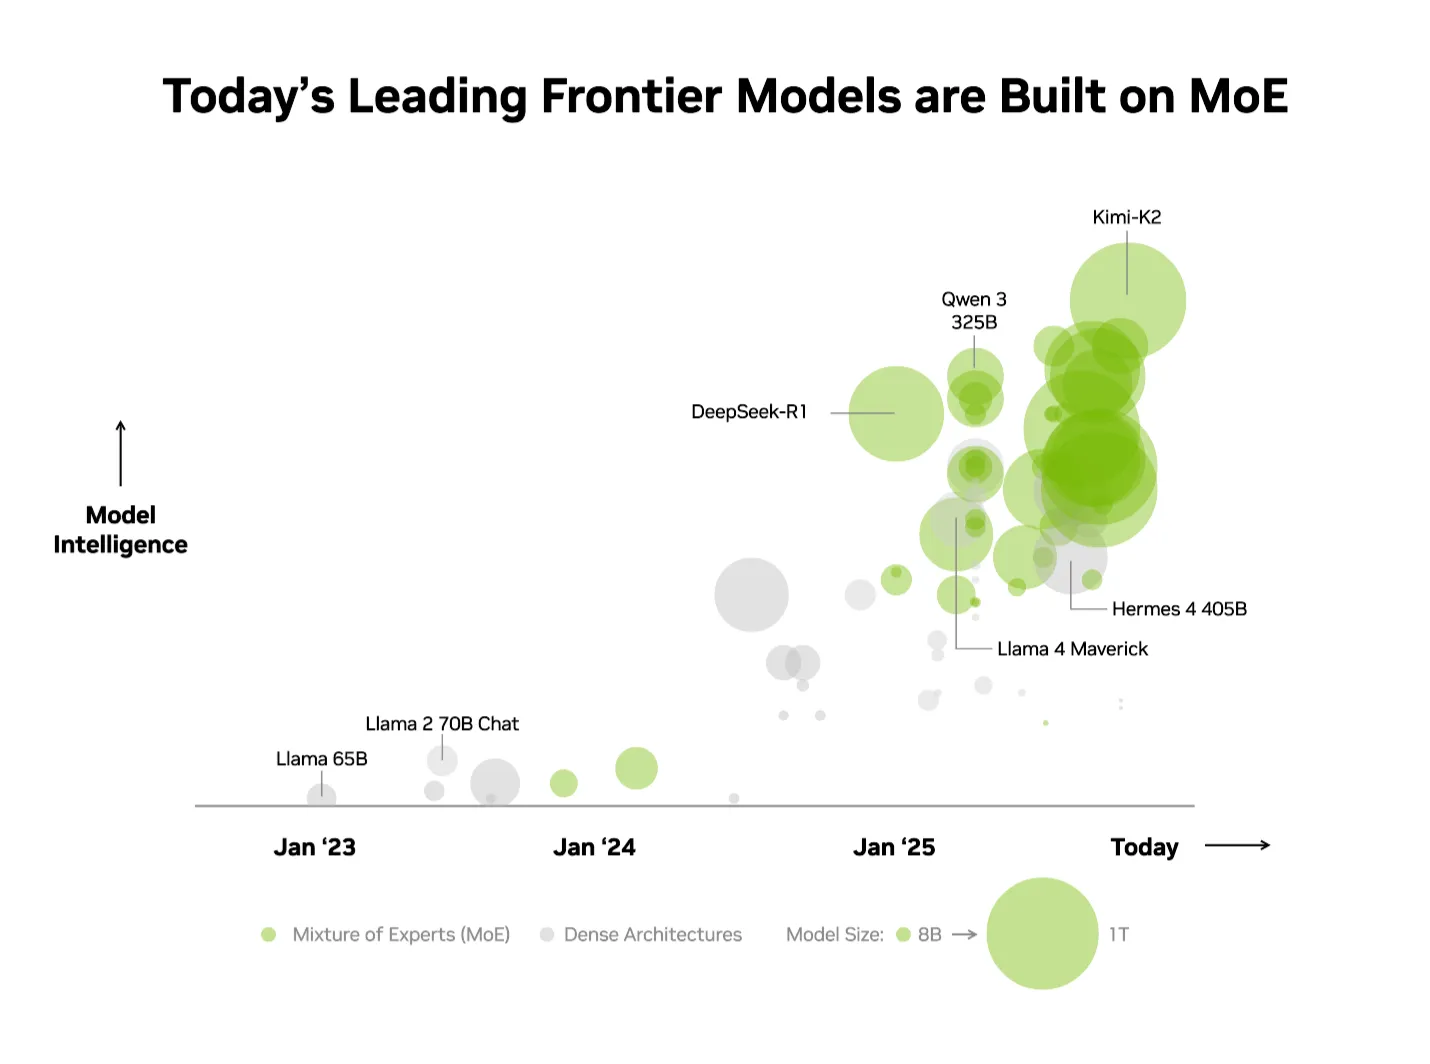
That efficiency advantage has already reshaped the open-source landscape, as the entire top 10 on the Artificial Analysis leaderboard now uses MoE, including DeepSeek-R1, Kimi K2 Thinking, OpenAI’s gpt-oss-120B and Mistral Large 3.

But while the architecture itself is elegant, scaling it in production is notoriously tough. You can’t fit a frontier MoE model onto a single GPU, so the experts have to be spread across multiple GPUs in a setup called expert parallelism. On platforms like NVIDIA’s H200, this creates serious bottlenecks: GPUs repeatedly pulling expert parameters from memory, or struggling with the high-latency all-to-all communication needed to stitch the experts’ outputs together.
NVIDIA’s answer is extreme codesign, which is where the GB200 NVL72 system comes in. By linking 72 Blackwell GPUs over a massive NVLink fabric with 30TB of shared memory and 130 TB/s of connectivity, NVL72 effectively lets MoE models scale without running into traditional memory and networking limits. In practice, it reduces the number of experts per GPU, lightens memory pressure, accelerates inter-GPU communication and even uses the NVLink Switch to help with compute. Frameworks like TensorRT-LLM, vLLM and especially SGLang build on this foundation to unlock meaningful inference gains.
You can see the results in real benchmarks. Kimi K2 Thinking, currently the most intelligent open-source model, gets a 10x performance boost on NVL72 compared with H200. DeepSeek-R1, Mistral Large 3 and the rest of the major MoE-based frontier models see similar leaps, which directly translate into better user experiences and dramatically lower per-token cost. Cloud providers like AWS, Google Cloud, CoreWeave, Azure, Lambda and others are already rolling out GB200 NVL72 racks to support customers deploying MoE in production. Companies like DeepL and Fireworks AI are validating the gains as they train and serve next-generation MoE models on Blackwell hardware.
What’s interesting is that this isn’t just about today’s text models. The emerging wave of multimodal and agentic systems rely on the same core pattern of routing tasks to specialized components, just like MoE. As enterprises begin running multiple models and agents simultaneously, NVIDIA’s vision of a shared expert pool makes the economics even more compelling: instead of duplicating entire models, you route requests to the experts best suited for each job.
In other words, mixture-of-experts has become the architecture powering the modern frontier, and NVIDIA’s GB200 NVL72 shows what it looks like when the hardware stack is shaped precisely for that future. And with the company’s roadmap extending toward the Vera Rubin architecture, the industry is clearly settling into an era where scale, efficiency and capability grow side by side.


